Xiaomeng Qian (钱晓萌)
I am a first-year PhD student at Fudan University, working with the OpenMOSS team under the supervision of Prof. Xipeng Qiu. Previously, I received my B.Eng. degree from the School of Software, Nanjing University. I conduct my research as a research intern at MOSI Intelligence (模思智能), where the MOSS-VL model family is built.
My research focuses on multimodal video understanding with large foundation models. I am broadly interested in building and improving multimodal foundation models, with the goal of enabling machines to perceive, comprehend, and reason over visual content — particularly in the video domain. My current work explores how to effectively integrate visual and linguistic information to advance video understanding capabilities.
I am a core contributor to the MOSS-VL model family, where I work on training data across the full pipeline — data infrastructure, assembly and delivery, and data synthesis — spanning both pre-training and post-training stages.

News
| Aug 15, 2026 | We released the MOSS-VL Technical Report, an open vision-language model family for real-time interaction! |
|---|---|
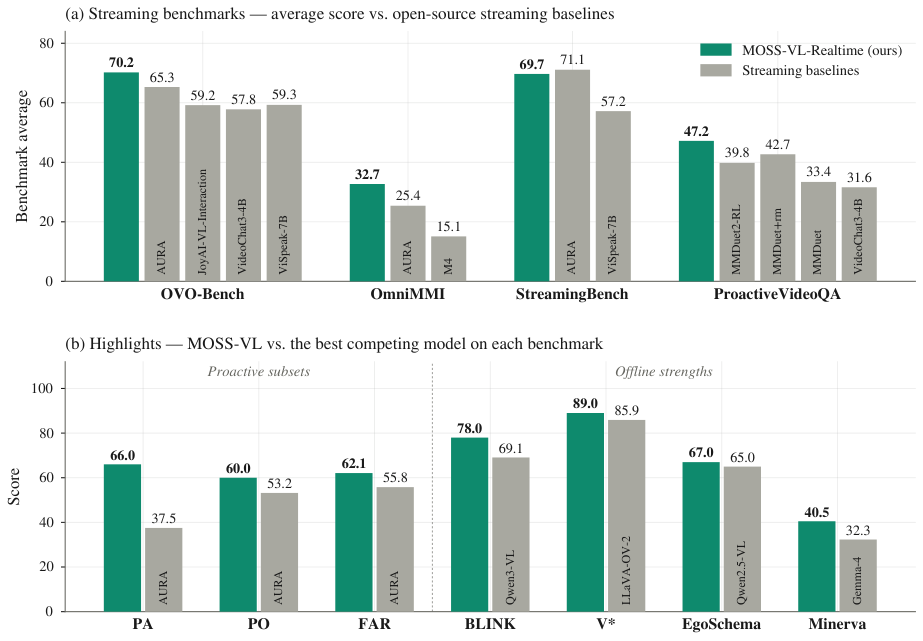
| Jul 08, 2026 | We released MOSS-VL-Realtime, achieving state-of-the-art real-time understanding! Check out our blog. |
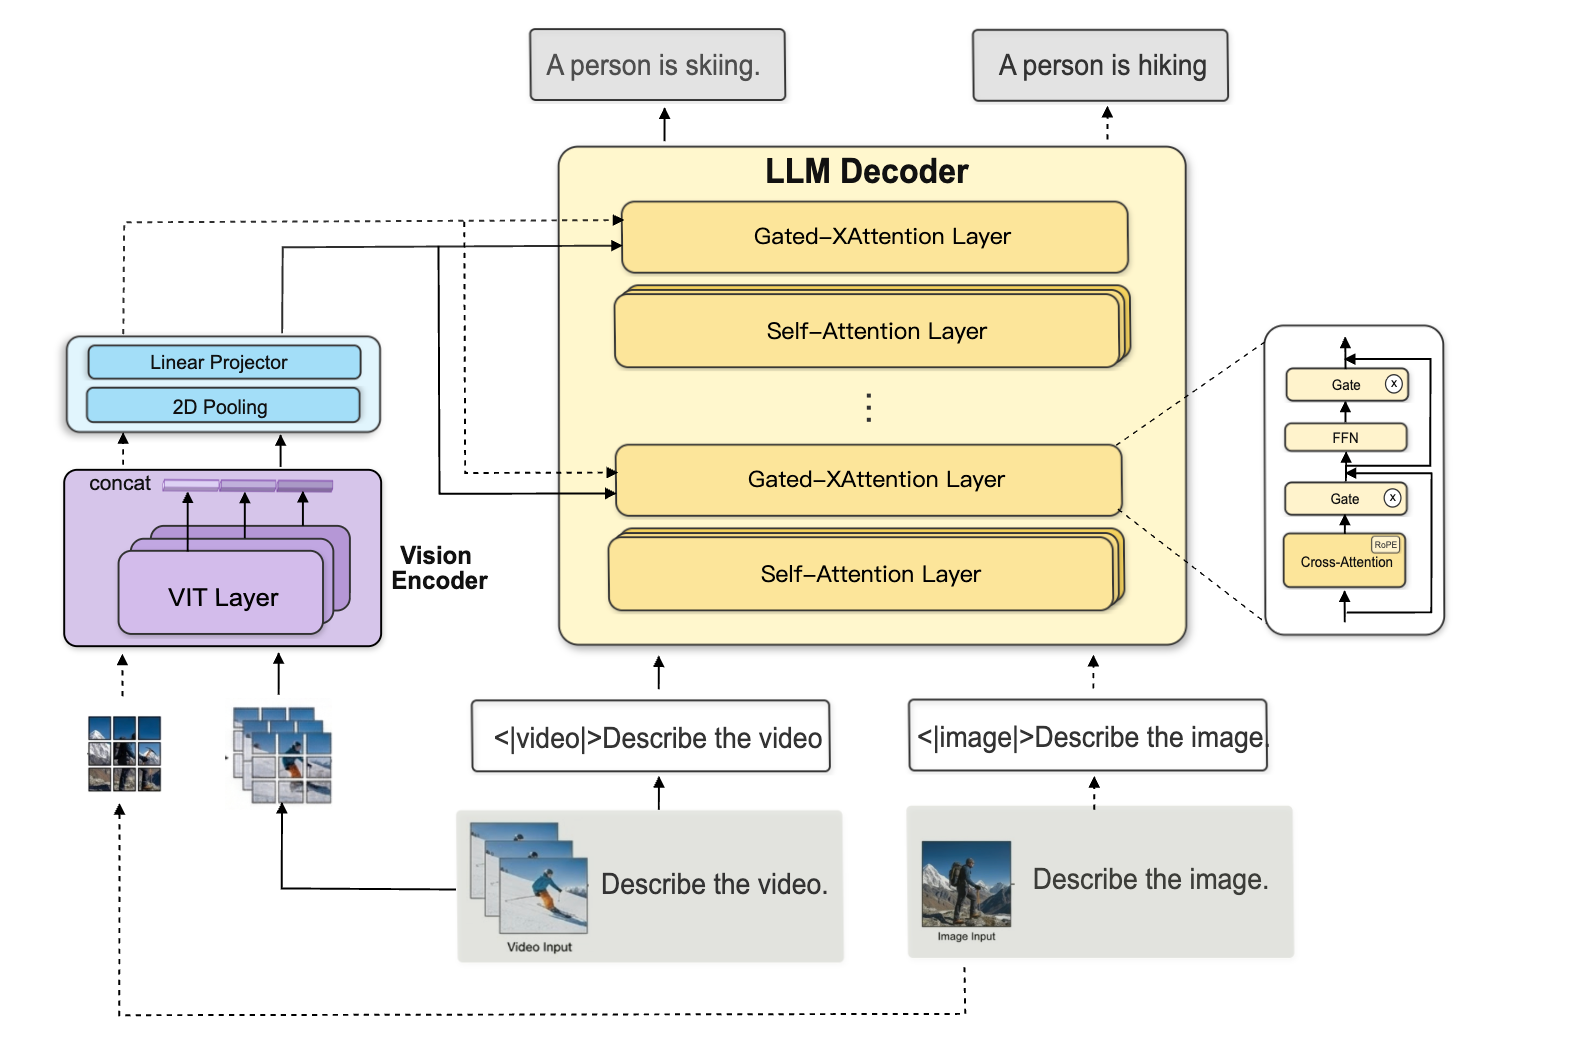
| Apr 08, 2026 | We officially released MOSS-VL! Check out our demo. |
| Mar 02, 2026 | Started an internship at MOSI Intelligence, working on the MOSS-VL project. |
| Jul 01, 2025 | Started an internship at the OpenMOSS team, working on MOSS-Video-Preview and MOSS-VL projects. |