Projects
Model releases I have contributed to as a member of the OpenMOSS team.
An open vision-language model family for real-time interaction
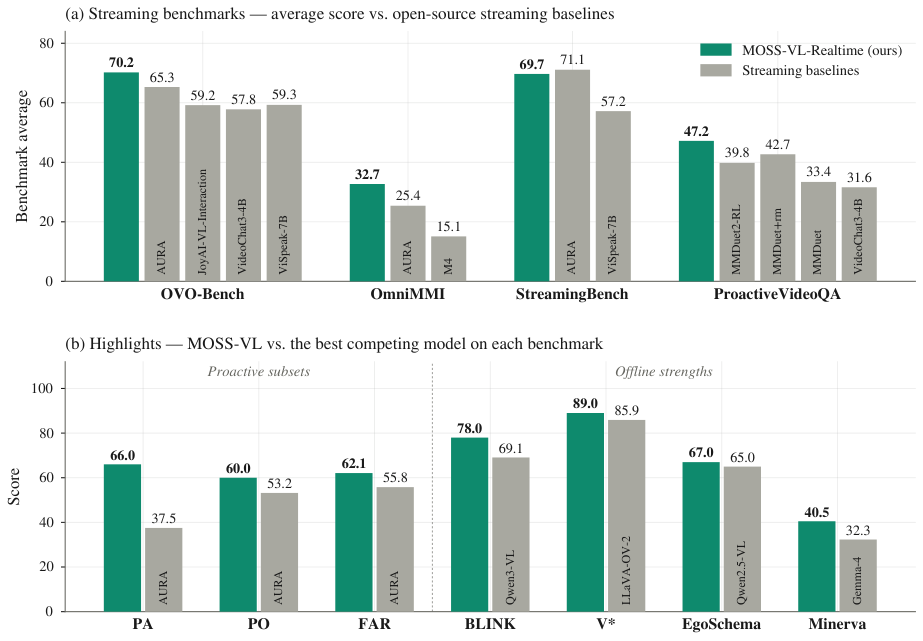
MOSS-VL-Realtime treats real-time interaction — perceiving while it speaks — as a first-class capability: gated cross-attention lets the model keep watching incoming frames while generating, and a synthesized interaction corpus supervises when to speak, stay silent, or revise. It posts the best average on three of four streaming benchmarks among open-source streaming models.
As a core contributor, my work on this release spanned data assembly, tooling, governance and synthesis:
- Owned training-data assembly and versioned delivery for pre-training stages 1–4 and SFT: dataset curation, token statistics, and mixture-ratio sampling
- Developed
asb, the team’s automated training-data assembly tool: config-file driven, per-bucket sampling, per-category deduplication, bitmap-based versioning and resumable assembly, with built-in caption/OCR and interleaved-QA augmenters - Co-designed the team’s data governance system: a dataset taxonomy of 32 categories with YAML-based configuration; migrated legacy datasets with old-to-new category mapping and model-assisted labeling
- Built homologous synthetic data for needle-in-a-haystack (NIAH) tasks, covering the 8 task types of MMLongBench’s NIAH track (text and image needles) — 100K samples for pre-training stage-4 annealing and 30K for SFT
An open vision-language model family for image and video understanding
MOSS-VL is an open vision-language model family for image and video understanding. Its offline model, MOSS-VL-Instruct, is competitive at comparable scale and leads temporal-reasoning video benchmarks.
As a core contributor, my work on this release covered the training-data stack — infrastructure, assembly and synthesis:
- Built the team’s training-data infrastructure: video/image/text preprocessing and deduplication pipelines, MongoDB schema iteration and data import/export flows
- Owned training-data assembly and versioned delivery for pre-training stages 1–4 and SFT: dataset curation, token statistics, and mixture-ratio sampling
- Designed and implemented image/video caption augmentation schemes (random perturbation, multi-image sequence expansion, multi-image collage, multi-video interleaving, etc.); restructured image-grounding data into multi-turn, multi-image form
- Ran the model identity data synthesis pipeline end to end, producing 200K samples for pre-training stage 4 (long-context and annealing) and 50K for SFT